Learn Inference
Curated by Learn Inference • Added 2026-07-01
An interactive guide to serving generative AI models in production
Learn Inference is an interactive handbook dedicated to inference engineering: how generative AI models are served at scale, from attention mechanisms and KV caching to paged memory, batching heuristics, and multi-GPU routing.

- ✓Inference lifecycle mechanics: prefill vs. decode phases and memory bandwidth bounds
- ✓KV cache footprint calculation, paged allocation strategies, and continuous batching
- ✓Attention kernel optimizations including FlashAttention-2, FlashDecoding, and TensorRT-LLM
- ✓Speculative decoding, model quantization (AWQ, FP8, INT4), and multi-cloud throughput economics
- ★Interactive compute and memory simulators
- ★Primary source citations and benchmarks
- ★Sleek, high-craft dark artboard design
Add the Learnlists badge to your website
Show visitors that Learn Inference is curated and listed on Learnlists. Paste the embed code on your landing page, docs, or footer to drive verified social proof.
Select Style
Pick Standard or Compact in Light or Dark.
Copy Snippet
Includes automatic attribution & canonical link.
Paste into HTML
Compatible with React, Astro, WordPress, Webflow.
Interactive preview · Click to verify target destination
Related in AI & Machine Learning
Other vetted resources in this discipline

TrenTorch
Build machine learning frameworks from scratch by hand

Fanout
Mapped technical learning across AI research, systems, and ML math

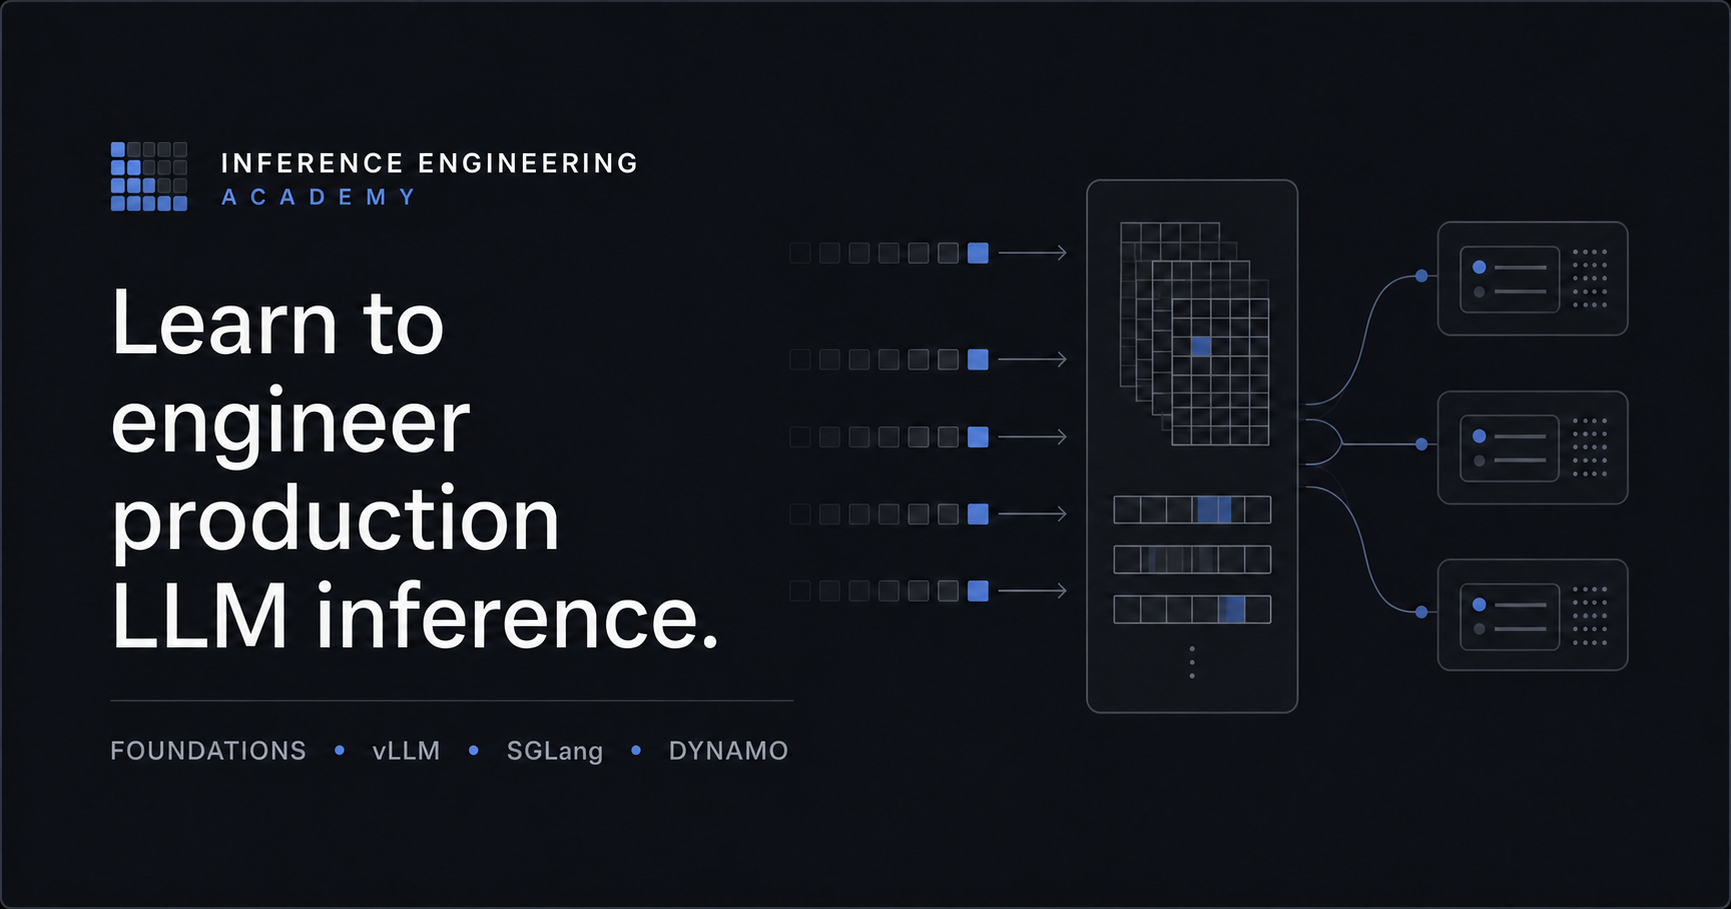
Inference Engineering
Deep-dive technical guide to LLM inference optimization & runtime mechanics