Inference Engineering
Curated by Inference Engineering • Added 2026-05-10
Deep-dive technical guide to LLM inference optimization & runtime mechanics
A comprehensive technical handbook explaining the hardware, memory hierarchies, KV cache optimizations, quantization algorithms, and vLLM architecture required to serve modern AI models.

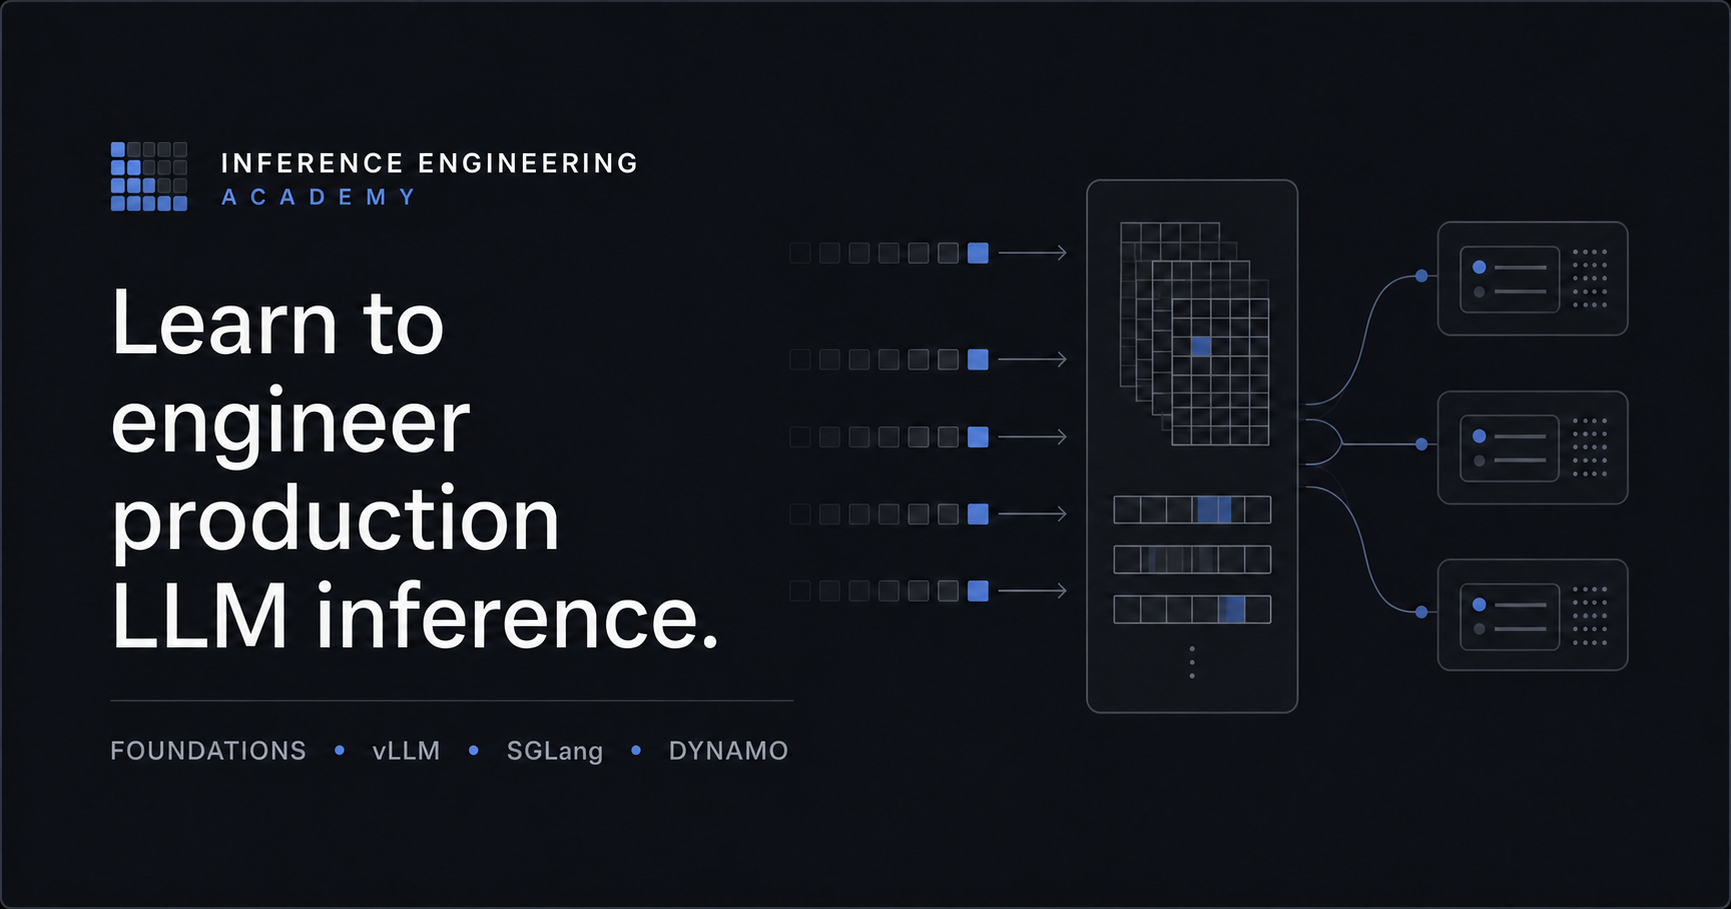
- ✓How memory bandwidth constraints dictate token generation throughput
- ✓PagedAttention, continuous batching, and chunked prefill mechanics
- ✓Weight and activation quantization techniques (AWQ, GPTQ, FP8)
- ✓Benchmarking inference engines across GPUs and edge hardware
- ★Detailed memory hierarchy diagrams
- ★Deep mathematical analysis
- ★Production infrastructure focus
Add the Learnlists badge to your website
Show visitors that Inference Engineering is curated and listed on Learnlists. Paste the embed code on your landing page, docs, or footer to drive verified social proof.
Select Style
Pick Standard or Compact in Light or Dark.
Copy Snippet
Includes automatic attribution & canonical link.
Paste into HTML
Compatible with React, Astro, WordPress, Webflow.
Interactive preview · Click to verify target destination
Related in AI & Machine Learning
Other vetted resources in this discipline

TrenTorch
Build machine learning frameworks from scratch by hand

Fanout
Mapped technical learning across AI research, systems, and ML math

AI Advent Calendar
25 interactive daily lessons to master modern generative AI concepts